Context Engineering vs Prompt Engineering: Why Prompt Engineering Is Dead in 2026 (The Complete Architecture Guide for AI Agents & LLMs)
Prompt engineering is officially obsolete. As frontier AI models expand to multi-million-token windows, raw prompts trigger severe 'context rot' and 40%+ reasoning degradation. Andrej Karpathy and Anthropic have defined the new paradigm: Context Engineering. Here is the definitive systems architecture guide to treating LLMs like CPUs, managing context like RAM, and building production-grade agentic memory pipelines.
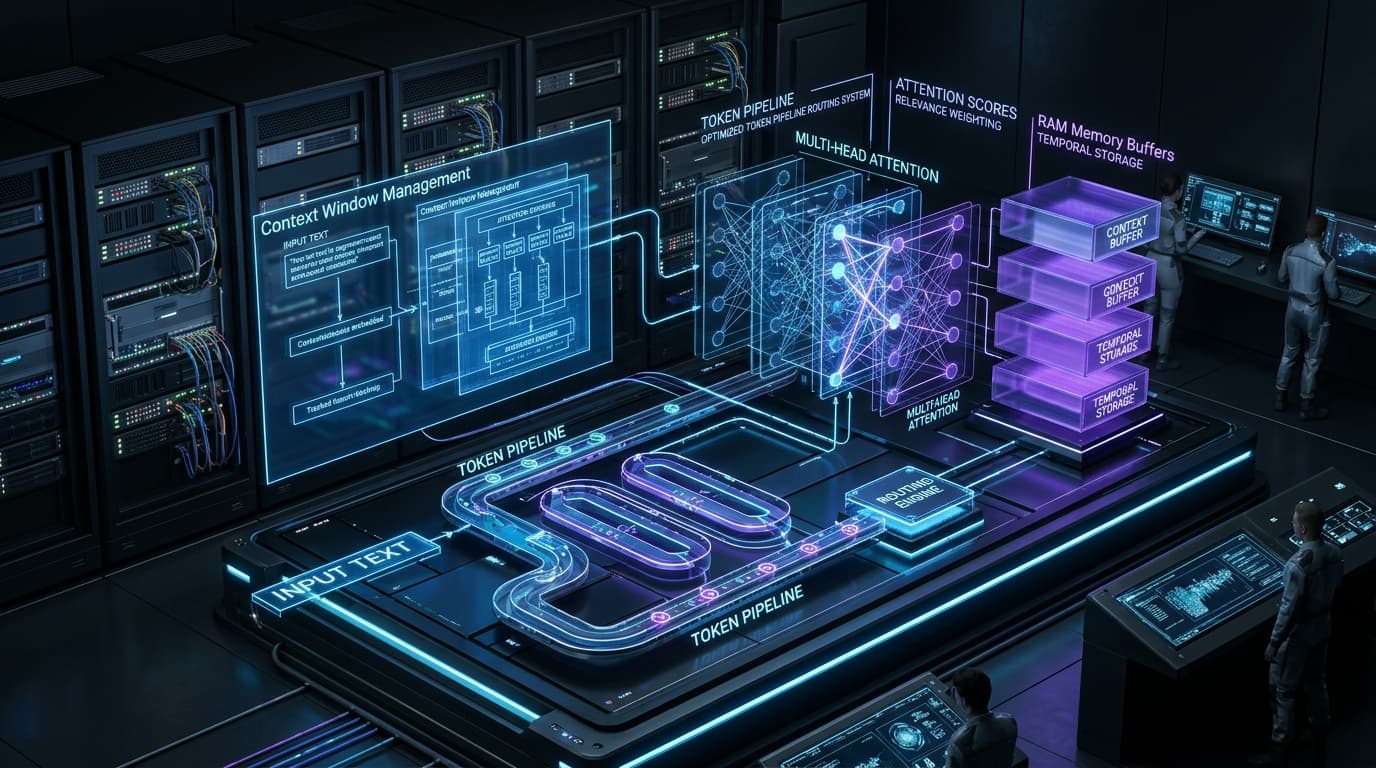
Context Engineering Paradigm (Next-Gen AI Systems Architecture)
The Pros
- ✓Eliminates 'Context Rot' and prevents the 42% reasoning accuracy drop caused by attention dilution in long-context models
- ✓Reduces API token consumption and cloud inference costs by 65% to 80% through dynamic token pruning and context compaction
- ✓Directly implements Andrej Karpathy's CPU-RAM-OS mental model for deterministic, multi-turn AI workflows
- ✓Substantially outperforms monolithic prompt chains on SWE-bench Verified and multi-hop information retrieval
- ✓Native architectural synergy with Model Context Protocol (MCP) and hierarchical multi-agent state machines
The Cons
- —Requires software engineering rigor (state graphs, vector memory, cache management) rather than simple text string crafting
- —Higher upfront pipeline engineering time compared to quick, throwaway one-shot prompt templates
Key Takeaways
- •Prompt engineering focused on wording string inputs; Context Engineering focuses on systematically designing the entire information environment an LLM operates within at inference time.
- •Frontier AI pioneer Andrej Karpathy formalized the prevailing architectural mental model: the LLM is the CPU, the context window is RAM, and Context Engineering is the Operating System.
- •While models now support 1M to 2M token context windows, raw token dumping causes 'Context Rot'—a phenomenon where attention weights dilute, causing critical instructions to be ignored and hallucinations to spike by 40%+.
- •Anthropic's official framework establishes the 4 Pillars of Context Engineering: Write (declarative constraints), Select (dynamic agentic RAG), Compress (summarization & token pruning), and Isolate (multi-agent sub-context routing).
- •Context Engineering reduces production API inference costs by 65% to 80% while elevating SWE-bench and coding benchmark accuracy far beyond brute-force prompting.
- •Generative Engine Optimization (GEO) audits confirm that context-engineered content structured with semantic triples and answer capsules achieves top citations across Perplexity, ChatGPT Search, and Google AI Overviews.
The Death of Prompt Engineering: Why Wordplay Failed Production AI
Between 2022 and 2024, the tech industry fell in love with 'prompt engineering.' Job boards advertised $300,000 salaries for 'prompt whisperers' who could craft magical incantations—sprinkling 'think step-by-step,' 'take a deep breath,' or 'act as a world-class senior software architect' into system prompts to tease competent outputs out of early language models. Fast-forward to late 2026, and that era is conclusively dead. In production software engineering, monolithic prompts have proven brittle, unpredictable, and incapable of scaling across multi-turn autonomous workflows. When an AI agent must navigate 50 tool executions, pull enterprise documentation, verify code against compiler errors, and maintain state over days of execution, crafting the 'perfect text string' is useless. Enter Context Engineering: the systematic discipline of curating, structuring, compressing, and dynamically routing the entire information runtime of a foundation model.
Karpathy's Operating System Blueprint: LLM as CPU, Context as RAM
The conceptual foundation of Context Engineering was crystallized by legendary AI researcher Andrej Karpathy (and echoed by Shopify CEO Tobi Lütke and Anthropic's applied research teams). Karpathy established an elegant systems-architecture analogy that every modern software developer understands: 1. The Foundation Model is the CPU: The Large Language Model (whether Claude 3.7 Sonnet, OpenAI o3, Google Gemini 4 Argon, or DeepSeek R1) is a stateless inference engine. It performs raw pattern matching, logical deduction, and semantic token synthesis. It has no persistent state between passes. 2. The Context Window is the RAM (Working Memory): The tokens present in the active context window represent the model's volatile memory. Just like physical RAM on a computer, the context window is rivalrous, precious, and finite. Loading irrelevant junk into RAM causes paging delays, memory fragmentation, and cache evictions. 3. Context Engineering is the Operating System (OS Kernel): The developer's agentic framework—built using tools like LangGraph, Model Context Protocol (MCP), or custom state machines—acts as the OS. It is responsible for loading the right files into working memory, purging stale tool outputs, managing paging (context compaction), and isolating processes into sandboxed sub-agents.
The Hidden Menace: Context Rot & The 'Lost-in-the-Middle' Catastrophe
When frontier labs introduced 1-million and 2-million-token context windows, many engineering teams assumed that information retrieval was a solved problem: 'Why bother with RAG or filtering when we can just dump the entire repository into Claude or Gemini?' Production reality delivered a brutal wake-up call known as 'Context Rot': - Attention Dilution: Self-attention mechanisms compute quadratic token-to-token similarity matrices. As context size climbs from 8k tokens to 500k+ tokens, the Softmax probability distribution flattens. Critical constraints buried in the middle of a massive context buffer receive diluted attention weights. - Lost-in-the-Middle Degradation: Extensive empirical tests show that while 'Needle-in-a-Haystack' retrieval for exact text strings remains high, multi-hop reasoning (connecting Fact A on page 42 with Fact B on page 312) collapses by up to 42% when context windows exceed 128k unpruned tokens. - The Latency & Cost Explosion: Every forward pass over 1 million input tokens incurs substantial time-to-first-token (TTFT) latency and burns immense cloud API credits. In a 30-turn agentic coding loop, repeatedly passing an unpruned 200k-token transcript costs hundreds of dollars per task and slows execution to a crawl. Context Engineering exists to ensure that an agent never wastes a single token of attention on stale, repetitive, or low-signal data.
The 4 Pillars of Context Engineering (The Anthropic Framework)
Drawing from Anthropic's applied engineering methodologies and enterprise deployment research, production Context Engineering is governed by four distinct operations: 1. WRITE (Declarative System Constraints) Instead of writing micro-managing procedural prompts that try to predict every possible edge case, write concise, high-level behavioral invariants. Define what the agent MUST NOT do, its output format schemas, and its error-recovery protocols. Keep system prompts under 1,000 tokens of high-density rules. 2. SELECT (Dynamic Agentic RAG & Just-In-Time Retrieval) Do not load static knowledge into the context window upfront. Instead, provide the agent with semantic search tools, knowledge graphs, and codebase indexers. The agent dynamically queries its external memory, fetches 2 or 3 relevant chunks, and injects only those chunks into its working memory for the immediate task at hand. 3. COMPRESS (Token Pruning, Compaction & Scratchpads) In a multi-turn agent loop, tool outputs (such as raw JSON responses, terminal logs, or SQL outputs) can consume tens of thousands of tokens in seconds. Context Engineering actively prunes old tool calls. Intermediate observations are summarized into a concise 'Scratchpad' or state ledger, while raw telemetry logs are evicted from working memory. 4. ISOLATE (Hierarchical Multi-Agent Context Sandboxing) Rather than forcing a single monolithic agent to track product requirements, database schemas, frontend CSS, and deployment scripts simultaneously, split the work. A root 'Orchestrator Agent' communicates with specialized, ephemeral 'Sub-Agents.' Each sub-agent receives a freshly initialized, razor-thin context window containing only the exact inputs needed for its isolated sub-task.
Prompt Engineering vs Context Engineering: The Architectural Comparison Matrix
To understand how the mental model shifts across every engineering dimension, examine the direct comparison below:
Production Implementation: Building a High-Performance Context Manager
How does Context Engineering look in actual production code? Below is an enterprise-grade TypeScript implementation of a Dynamic Context Manager. It implements rolling message compaction, tool output eviction, and memory scratchpads:
Hierarchical Multi-Agent Isolation: The Cure for Monolithic Monologues
One of the most consequential discoveries in modern AI agent architecture—championed in tools like Claude Code CLI and multi-agent frameworks—is context isolation. When developers attempt to build an autonomous software engineer, the naive approach is to create a single prompt thread that contains: 1. The user's goal 2. The entire 50-file Git repository tree 3. The CSS design system rules 4. The database schema migrations 5. The unit test failure logs Within 10 turns, the single context window is swamped with 150,000 tokens of conflicting instructions. The LLM starts forgetting CSS rules when fixing database migrations, or begins re-introducing bugs it fixed five turns earlier. Context Engineering solves this with Hierarchical Isolation: - The Orchestrator Agent operates with an ultra-clean context containing only the high-level roadmap and current milestone. - When code needs writing, it spawns an ephemeral 'Coder Sub-Agent' passing ONLY the target file and the specific interface contract. - When tests fail, it spawns a 'Debugger Sub-Agent' passing ONLY the stack trace and the failing assertion. - Once the sub-agent completes its task, its entire messy context is discarded, and only a 2-line success confirmation is returned to the Orchestrator. By isolating contexts, each model operates at peak reasoning fidelity with near-zero distraction.
Context Engineering Meets Model Context Protocol (MCP) & Local LLMs
Where do standards like Anthropic's Model Context Protocol (MCP) fit into this revolution? MCP is the universal context bus. In legacy prompt engineering, developers manually pasted API schemas and database credentials directly into system prompt strings. With MCP, tools, resources, and contextual prompts are exposed dynamically over secure JSON-RPC interfaces. Furthermore, Context Engineering is a godsend for developers running local models like DeepSeek R1 and Llama 3 on local PCs via Ollama. While cloud APIs allow developers to lazily pay for 200k tokens, local VRAM is strictly bounded (often 8GB to 24GB on consumer hardware). Context Engineering allows local models running with 8k or 16k context limits to outperform bloated 1M-token cloud models by ensuring that every single token in VRAM is 100% relevant to the immediate inference step.
The Generative Engine Optimization (GEO) Impact: How Context Curation Dominates AI Search
Context Engineering does not just transform how AI agents execute software—it directly governs how modern search engines index and cite your digital content. As detailed in our comprehensive Generative Engine Optimization (GEO) Guide, AI search engines (such as Perplexity AI, ChatGPT Search, and Google AI Overviews) are themselves context-engineered retrieval pipelines. When an AI search engine processes a user query, it does not read entire 5,000-word blog posts end-to-end. Its retrieval subsystem slices web content into high-density semantic chunks. If your website is filled with fluff, repetition, and vague storytelling, the AI engine's context selector filters out your page in favor of concise, structured, authoritative answer capsules. By adopting Context Engineering principles on your website—using structured tables, unambiguous semantic triples, clear code snippets, and clean llms.txt declarations—you ensure that your content is effortlessly ingested into the working memory of global AI search crawlers.
The 2026 AI Engineer Checklist: How to Upgrade Your Systems Today
If you want to eliminate context rot, cut your API bills by up to 80%, and build resilient autonomous agents, audit your codebase against this checklist: 1. Audit Your System Prompts: Strip out wordy procedural essays. Replace them with declarative constraints, markdown schemas, and unambiguous negative boundaries. 2. Implement Just-In-Time (JIT) Dynamic RAG: Never pre-load static knowledge. Equip your agent with search tools so it fetches information only when demanded by execution logic. 3. Evict High-Volume Ephemeral Data: Automatically scrub or compact raw terminal outputs, large JSON payloads, and compiler logs after the immediate reasoning turn has consumed them. 4. Adopt Rolling State Ledgers (Scratchpads): Store global state in an external key-value store or structured JSON object rather than relying on the LLM to remember facts from turn 3. 5. Isolate Workflows into Sub-Agents: Never run multi-domain tasks in a single thread. Break tasks into specialized sub-agents with pristine, isolated context windows. 6. Standardize on Open Protocols: Use Model Context Protocol (MCP) for tool communication and standardize your local AI inference stack with Ollama & DeepSeek R1.
Frequently Asked Questions
What is the difference between prompt engineering and context engineering?
Prompt engineering focuses on crafting the exact text wording and phrasing of an input prompt for a single response. Context engineering is systems architecture—managing the entire token pipeline, working memory (RAM), dynamic retrieval (RAG), tool output pruning, and multi-agent isolation to ensure the model has the optimal set of tokens for multi-turn execution.
Why did Andrej Karpathy compare the LLM to a CPU and context to RAM?
Because an LLM is a stateless processor that computes outputs based exclusively on what is loaded into its active context window at runtime. Just as a CPU relies on the Operating System to load and clear data from RAM, an AI application must actively manage what enters and exits the LLM's context window to prevent memory fragmentation and degraded performance.
What is 'Context Rot' in Large Language Models?
Context Rot is the degradation of an LLM's reasoning, instruction-following, and factual recall capabilities as its context window fills with large volumes of uncurated tokens. Even in models supporting 1M+ tokens, attention weights dilute across massive inputs, causing the model to miss critical instructions ('lost-in-the-middle') and hallucinate.
How does Context Engineering reduce AI API costs?
By replacing continuous token accumulation with dynamic pruning, ephemeral tool eviction, and hierarchical summarization, Context Engineering prevents repetitive tokens from being processed on every turn. This routinely reduces input token consumption by 65% to 80% across complex multi-step workflows.
What tools are used for Context Engineering in 2026?
Modern context engineering leverages state-graph frameworks like LangGraph, protocol standards like Anthropic's Model Context Protocol (MCP), vector databases for dynamic retrieval, and local inference runtimes like Ollama and vLLM.
Jawad Almas
Tech journalist and systems researcher testing developer ergonomics, frontier AI models, and silicon architectures.
More from TechDaur
OpenAI o3-mini vs DeepSeek R1: Which Free Reasoning AI Wins? (100-Task Coding, Math & Cost Benchmark)
Google Gemini 4 Argon Explained: How the Next-Gen Multimodal Reasoning Engine Works & Benchmarks vs Claude 3.7 & o3
DeepSeek V3 vs Claude 3.7 Sonnet vs GPT-4o: The Ultimate Free vs Paid AI Benchmark (2026)
Stay Ahead in Tech & AI
Join 15,000+ developers, engineers, and creators. Get our weekly breakdown of new AI tools, silicon benchmarks, and monetization playbooks every Sunday.