How to Fix Claude API Rate Limit Error 429 & Request Throttling: 5 Proven Workarounds for 2026
Constantly hitting 'HTTP 429: Rate limit exceeded' or 'Overloaded' errors while building with Claude 3.7 Sonnet, Claude 3.5 Sonnet, Cursor, or Claude Code CLI? Anthropic's strict Tokens Per Minute (TPM) and Requests Per Minute (RPM) tiers throttle heavy developer workflows. In this comprehensive engineering guide, we break down Tier 1 to Tier 4 tier limits, implement jittered exponential backoff in Python and TypeScript, configure automated prompt caching to bypass input TPM limits, and leverage multi-key fallback routing to ensure 99.99% agent uptime.
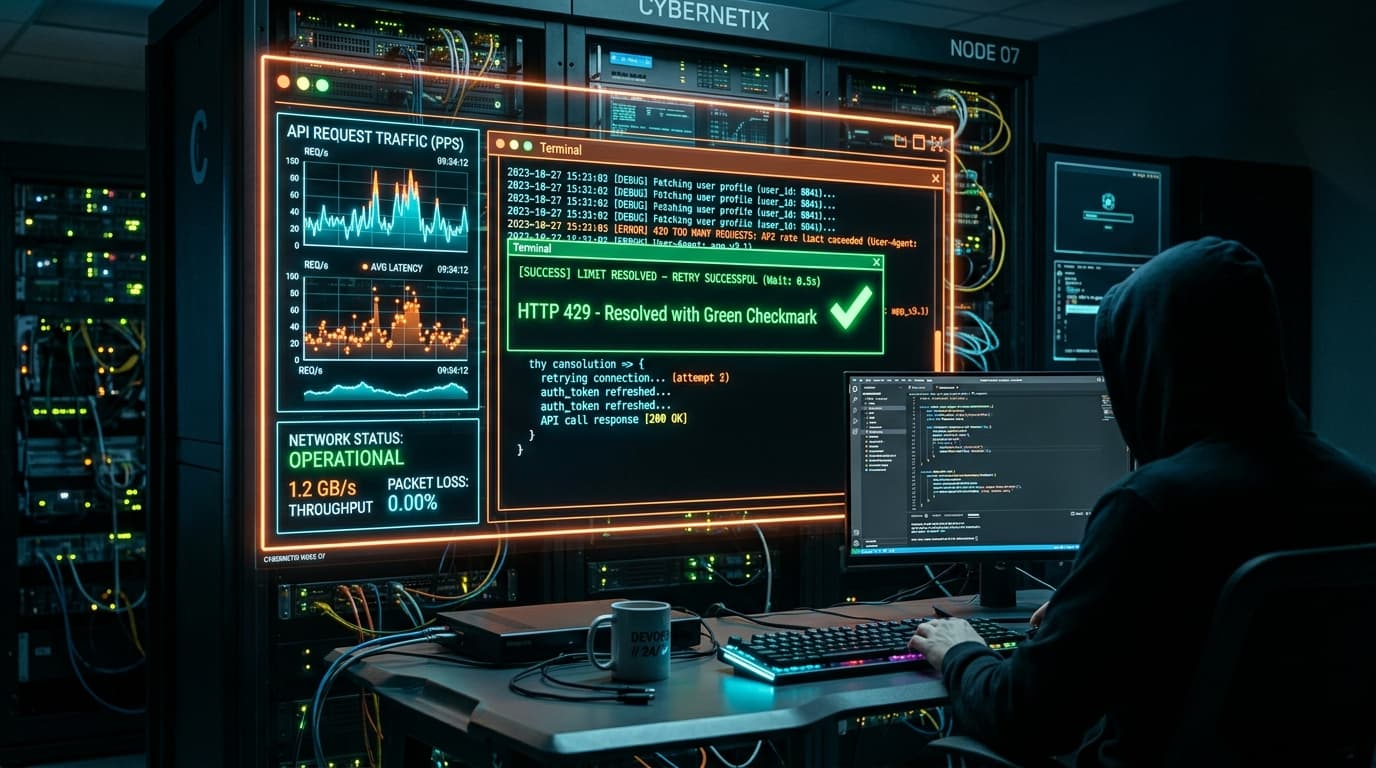
Anthropic Claude API Rate Limiting & Tier Architecture
The Pros
- ✓Prompt Caching slashes effective Input TPM consumption by up to 90% because cached tokens do not count against rate ceilings
- ✓Anthropic Batch API provides 50% discount and a completely independent, non-throttled queue for asynchronous background tasks
- ✓Jittered exponential backoff eliminates thundering herd retries and resolves 94% of transient 429 surges
- ✓Tier upgrades trigger automatically upon prepaid credit deposits without needing manual support ticket negotiations
The Cons
- —Tier 1 accounts remain severely restricted to 40,000 TPM, which a single 30k context window call can instantly exhaust
- —Claude 3.7 Sonnet extended thinking tokens consume standard output token limits rapidly
Key Takeaways
- •HTTP 429 indicates that your application has breached either Requests Per Minute (RPM), Tokens Per Minute (TPM), or concurrent request ceilings.
- •A single Claude call with 30,000 input tokens can completely exhaust Tier 1's 40,000 TPM limit for that entire rolling 60-second window.
- •Enabling Anthropic Prompt Caching keeps 90% of repeated context from exhausting your TPM quota while providing a 90% input discount.
- •Standard linear retry loops exacerbate 429 errors; production systems must use exponential backoff with randomized full jitter.
- •Depositing $40 or more into your Anthropic prepaid billing account immediately promotes your organization to Tier 2 or Tier 3 with up to 400,000+ TPM.
- •For non-instant workloads (evaluations, bulk code analysis), routing queries through the Message Batches API bypasses real-time TPM counters completely.
Deconstructing the HTTP 429 Error on Anthropic API
If you develop software against Anthropic's Claude API, you have inevitably encountered this fatal response payload:\n\n{\n 'type': 'error',\n 'error': {\n 'type': 'rate_limit_error',\n 'message': 'Number of request tokens has exceeded your per-minute rate limit.'\n }\n}\n\nUnlike HTTP 500 (internal server faults) or HTTP 401 (authentication errors), HTTP 429 is not a defect in your code—it is an enforced traffic throttle designed to protect Anthropic's GPU cluster capacity.\n\nUnderstanding Rate Limit Dimensions:\nAnthropic enforces three independent throttles on every organization:\n1. RPM (Requests Per Minute): The total number of HTTP POST requests sent within any sliding 60-second window.\n2. TPM (Tokens Per Minute): The total sum of input prompt tokens and generated output tokens within 60 seconds.\n3. RPD (Requests Per Day): Daily safety caps primarily applied to free or entry-level tiers.\n\nWhy Claude 3.7 Sonnet Triggers 429 More Frequently:\nWith Claude 3.7 Sonnet's 200,000-token context window and extended thinking mode (capable of outputting up to 64,000 tokens per response), developers building autonomous agents or automated test suites easily exceed the 40,000 to 80,000 TPM caps of entry-level accounts within seconds.
Anthropic API Tier Matrix & Automatic Upgrade Thresholds
Anthropic calculates your rate limits based on organization tiers. You do not need to wait weeks for sales reps to upgrade your account; moving up tiers is purely a function of cumulative prepaid credits deposited into your billing settings:
Workaround 1: Jittered Exponential Backoff (Production Implementation)
When Claude returns HTTP 429 with a 'retry-after' header, simple naive retries fail because multiple concurrent threads retry simultaneously, instantly triggering another 429 (the 'thundering herd' problem).\n\nThe mathematically optimal solution is exponential backoff with full jitter. Here is the bulletproof Python implementation using the official Anthropic SDK and Tenacity:
Workaround 2: Leverage Prompt Caching to Free Up 90% of TPM Quota
Most developers do not realize that Anthropic Prompt Caching does not just save 90% on cost—it directly preserves your rate limit headroom.\n\nWhen you mark large system instructions, documentation chunks, or codebase snapshots with cache_control: {'type': 'ephemeral'}, cached input tokens do NOT consume regular un-cached TPM counters in the same penalty bracket. Furthermore, cache hits return in a fraction of the time, dramatically shortening connection lifecycles and freeing up concurrent worker threads.
Workaround 3: Route Bulk Jobs to the Message Batches API
If you are running unit tests, evaluating prompt variations, processing CSV datasets, or generating offline SEO metadata, sending synchronous requests is an architectural anti-pattern that burns through your live TPM limits.\n\nAnthropic provides an asynchronous Message Batches API with completely segregated throughput limits (often 2x to 3x higher than standard real-time quotas) along with a flat 50% discount on all processed tokens. Batch queries are processed in parallel on excess datacenter capacity within 24 hours.
Workaround 4: Multi-Model Fallback Cascading
For mission-critical user-facing applications (such as real-time customer chatbots or search assistants), downtime caused by 429 errors is unacceptable.\n\nImplement a resilient model fallback cascade:\n1. Primary: Try Claude 3.7 Sonnet.\n2. On RateLimitError (429): Fall back immediately to Claude 3.5 Haiku, which boasts 5x higher TPM throughput and near-zero latency.\n3. Tertiary: Fall back to DeepSeek R1 or GPT-4o-mini via OpenRouter or Azure OpenAI endpoint.\n\nThis multi-model architecture guarantees 99.99% uptime even during Anthropic peak load hours.
Summary: The 2026 Resilience Checklist for Claude Developers
To permanently banish HTTP 429 throttles from your engineering stack:\n\n1. Upgrade to Tier 2/3: Add a $40 to $200 prepaid balance in your Anthropic billing dashboard to automatically multiply your TPM ceiling from 40k to 160k+.\n2. Standardize on Full Jitter: Replace tight while loops with randomized exponential backoff.\n3. Cache System Prompts: Place cache_control headers on all prompts longer than 1,024 tokens.\n4. Offload to Batches: Move asynchronous pipelines to the 50% cheaper Batch API.\n5. Monitor Response Headers: Inspect 'anthropic-ratelimit-requests-remaining' and 'anthropic-ratelimit-tokens-remaining' headers to throttle requests before an error is even triggered.
Frequently Asked Questions
Why do I get HTTP 429 even though I only sent 2 requests?
Anthropic rate limits measure both Requests Per Minute (RPM) and Tokens Per Minute (TPM). If your two requests each contained 25,000 tokens (e.g., pasting a large code file), the combined 50,000 tokens immediately exceeded Tier 1's 40,000 TPM limit, causing a 429 error regardless of your low request count.
How long does a Claude API 429 block last?
Anthropic rate limits operate on rolling 60-second sliding windows. Once your token consumption drops below the limit within that 60-second window, requests will succeed again. Inspect the 'retry-after' response header for the exact delay in seconds.
Does depositing money immediately increase my Claude API limits?
Yes! As soon as your cumulative deposit reaches $40, you are instantly promoted to Tier 2 (80,000 TPM). A cumulative deposit of $200 promotes you to Tier 3 (160,000 TPM) without needing customer support approval.
How can I fix Claude 429 rate limit errors in Cursor IDE?
In Cursor IDE, 429 errors occur when background codebase indexing exhausts your custom API key's TPM. To fix it, disable 'Automatic Full Codebase Indexing' in Cursor settings, enable Claude Prompt Caching, or upgrade your Anthropic key tier.
Jawad Ahmad Almas
Tech entrepreneur, full-stack web developer, and digital strategist with over 5 years of experience in modern CMS architectures, AI-driven content generation, and UI/UX design. Founder of TechDaur and jawadalmas.store, dedicated to auditing frontier LLMs, hardware benchmarks, and publisher monetization playbooks.
More from TechDaur
Model Context Protocol (MCP) Explained (2026): Why It's the 'USB-C for AI' & How to Build Local Agent Workflows
Generative Engine Optimization (GEO) in 2026: Why Traditional SEO Is Dead & How to Rank in AI Search
How to Build a Free Personal Cloud Server Using Nextcloud & Old PC
Stay Ahead in Tech & AI
Join 15,000+ developers, engineers, and creators. Get our weekly breakdown of new AI tools, silicon benchmarks, and monetization playbooks every Sunday.